Open Source Intelligence (OSINT) in Legal Proceedings: Admissibility and Evidence in Indian Courts
Analysis of the legal admissibility of OSINT evidence under Indian law. Discover how digital footprints, social media forensics, air-space intelligence, and metadata satisfy Section 63 BSA criteria.
Cyber Forensics & Digital Evidence Collection under BSA, 2023: Section 63 Certificate Guide
Step-by-step legal and forensic guide to electronic evidence collection and certification under Section 63 of Bharatiya Sakshya Adhiniyam, 2023 (replacing Section 65B IEA). Mandatory checklist, format, and court defense.
DPDPA 2023 Compliance Checklist for Indian Startups: Data Protection & Privacy Requirements
An actionable 12-point DPDP Act 2023 compliance checklist tailored for Indian startups, SaaS companies, and mobile app developers. Protect your business from penalties up to ?250 Crore.
Supreme Court Cuts Judicial Service Practice Rule From 3 Years to 1 Year
Selected candidates will still spend two more years in training and clerkship before they're confirmed in the post. Here's how the new system works and why one judge on the bench wasn't fully convince...
How Indian Businesses Should Respond to Deepfake Threats Today: Why Your Business Needs to Care About Deepfakes Right Now!
A video surfaces online showing your CEO endorsing a competitor’s product. A voice recording allegedly captures your company’s confidential negotiations. An ima...
Protecting Children’s Data Under the DPDP Act: What EdTech, Gaming, Schools and Hospitals Need to Know Right Now
The notification of India’s Digital Personal Data Protection (DPDP) Act, 2023 marked a significant shift in how personal data is regulated domestically. But for...
Before India Builds More Data Centers, It Should Look at What Happened in the U.S.: Data Centers, AI, and Water
A. Introduction India is in the midst of an extraordinary infrastructure build-out. Government white papers describe a national ambition to turn the country int...
Agentic AI, Autonomous Decisions, and the US Liability Gap: What the Chambers 2026 Guide Reveals!
The question of accountability in AI-driven decisions is no longer theoretical. As autonomous systems move from research labs into supply chains, financial serv...
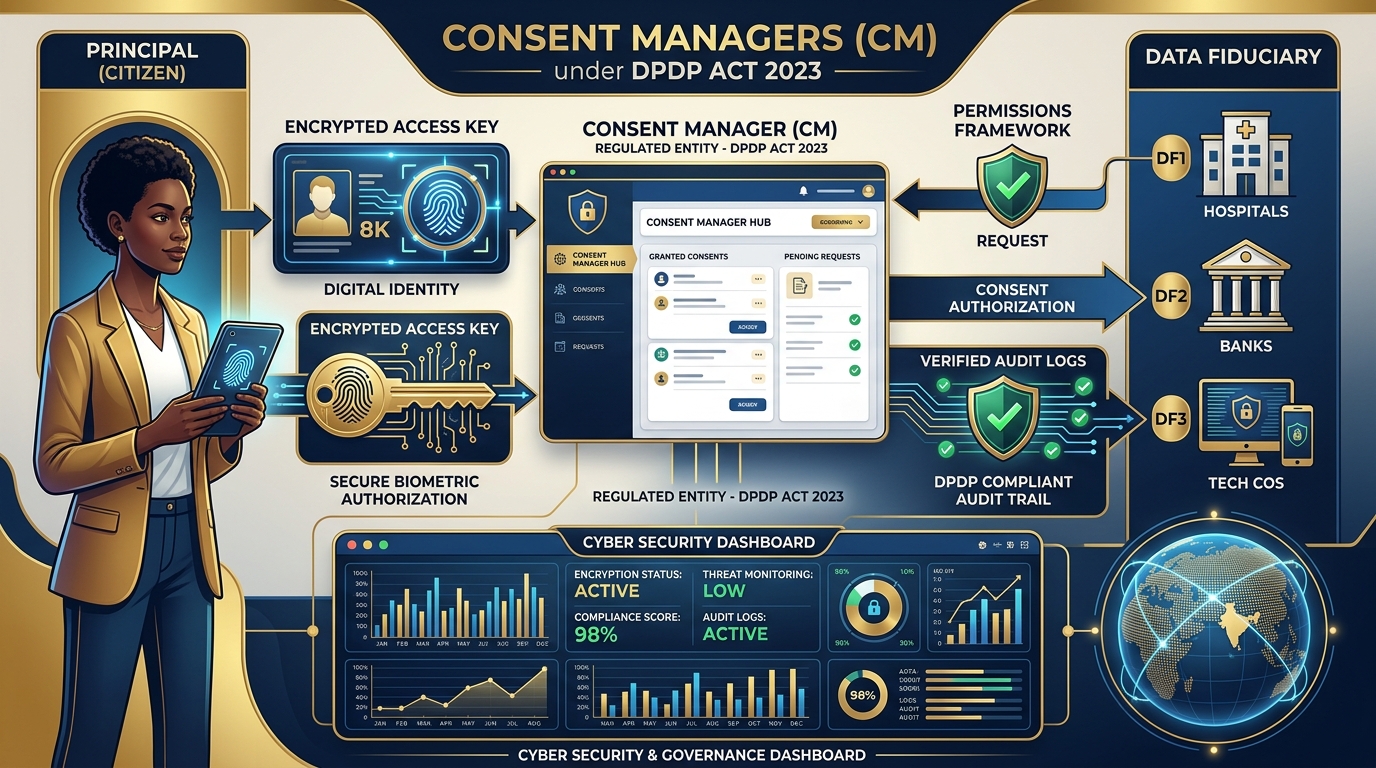
Consent Managers Under The Digital Personal Data Protection Act, 2023 And The Digital Personal Data Protection Rules: A Compliance Roadmap For Data Fiduciaries
Privacy Law Research | Technology Law Practice | June 2025 Abstract The Digital Personal Data Protection Act, 2023 (DPDP Act) introduces ‘Consent Managers’ as a...
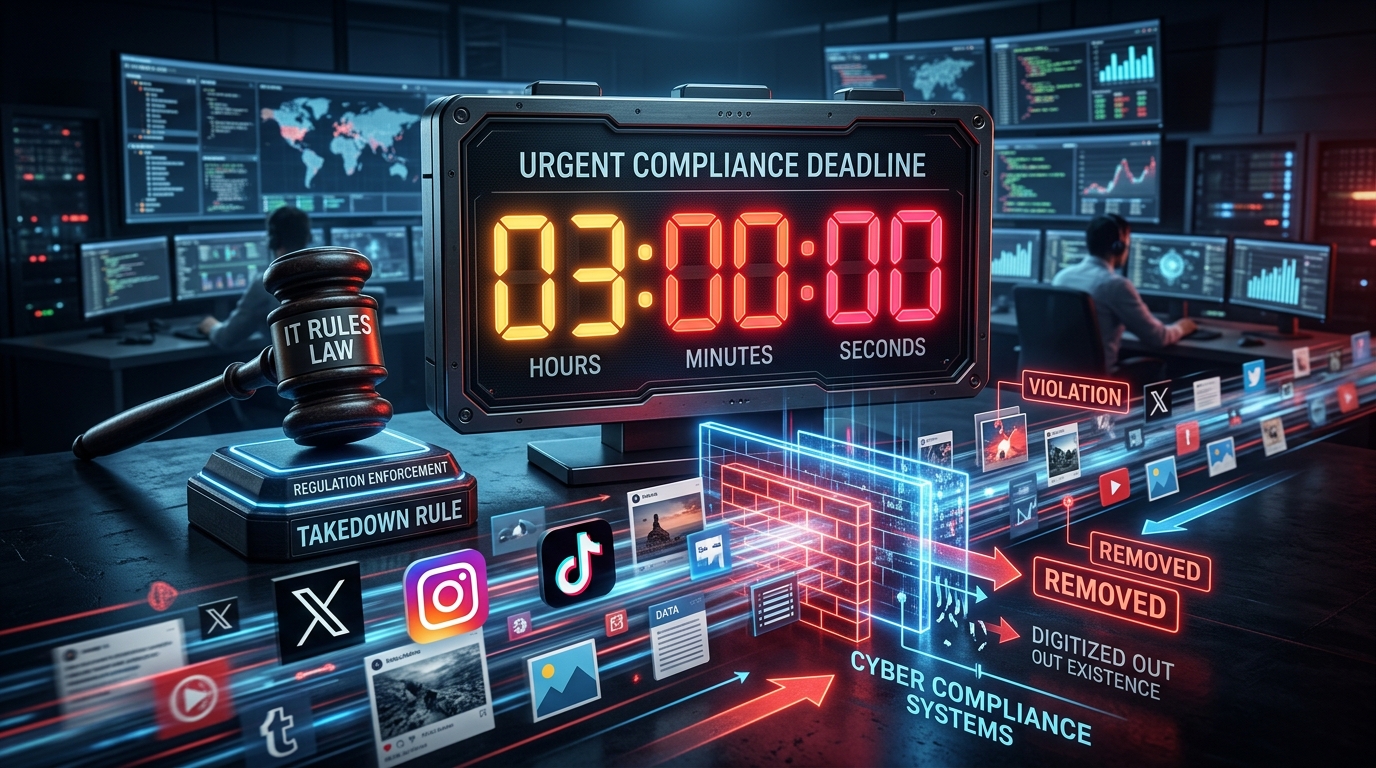
India’s 3 Hour Rule For Deepfake Notions Removal On Account Of Takedown Rule
THE ARTICLE OVERTHROWS LIGHT OVER THE INTERPLAY OF DEEPFAKE REGULATION IN ACCOUNT OF CURRENT FACETS AND IMPARTS AN CALL TO ACTION FOR THE VIEWERS TO WORK IN ALI...